Experience ExtractionAn experience contains more to learn from than its immediate verdict of success or failure.
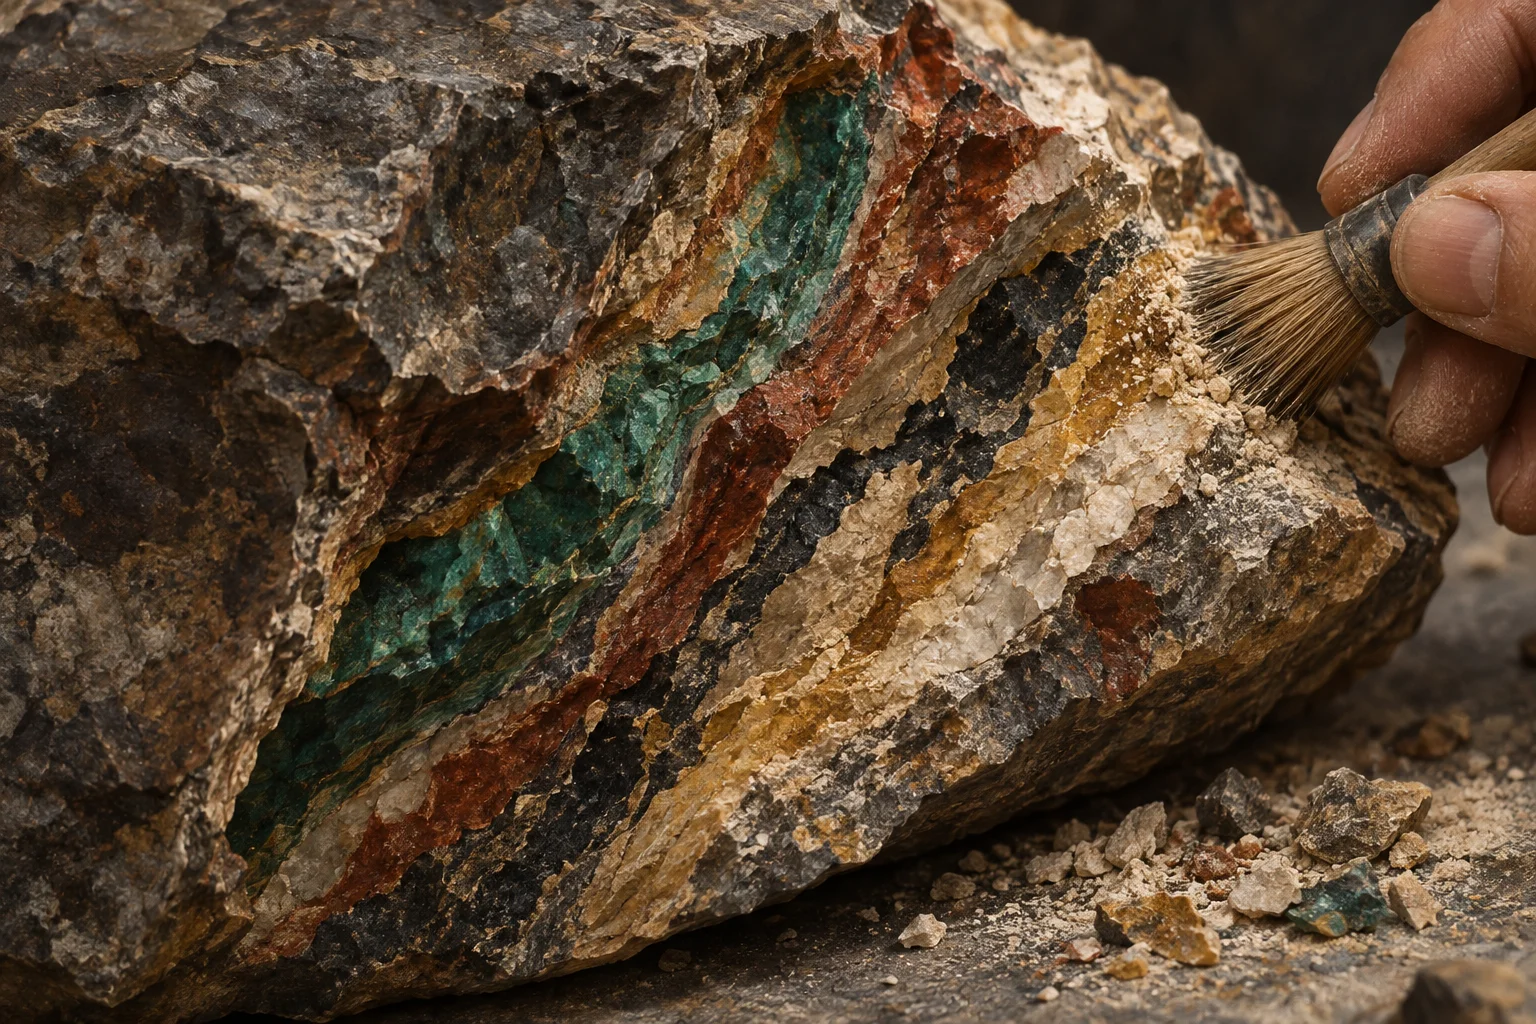
Experience as Hyperdimensional Ore
A three-month project can leave someone with little more than “that failed and felt bad.” The same project also contains decisions that caused trouble, alternatives that were available, and early signs that the work was going off course. Remembering the outcome does not preserve those details automatically.
Experience extraction means examining an experience closely enough that it changes your understanding and your next decision. Will developed the methods below while reactivating his gym routine, resuming work and creating content. His estimates of the methods' value come from comparing his early journals, which mostly recorded outcomes and feelings, with later journals that examined more of what happened.
The ore comparison expresses how much can remain unused: taking only the surface pebbles could leave most of the metal behind. Will estimates that recording only a surface narrative similarly captures only a small part of the available information, despite paying the full cost of the experience in time, energy and emotion. A prism offers another way to understand the operation: separating light makes its component frequencies available for inspection. Examining an experience from different directions makes information readable that an initial impression leaves implicit.
Those directions include what caused the outcome, what alternatives nearly happened, and what kind of situation it was. There may be a similar pattern in another domain. The sequence over time can reveal a turning point, while a mismatch with a prediction reveals something the earlier model missed. The emotional experience also contains information about what mattered and why.
A closer look
Keep the experience available for examination
The article offers several extraction methods; this sequence connects a few of them without assigning an invented learning multiplier.
Read this diagram
Record the event → Compare the prediction → Look for a pattern → Question the explanation → Choose a next test.
The Default: Surface Narrative Only
In the failed-project example, the team is demoralized and the budget has overrun. “Try something different” does not identify which decision to change. A market problem and an execution problem can produce the same disappointing result while requiring different responses.
A useful review reconstructs the decisions that generated each failure and the alternatives available at those points. It asks when the trajectory became unrecoverable and which warning appeared first. Comparing the outcome with the initial prediction shows what the team would now predict differently. Comparing the pattern with a relationship or health problem can reveal a structure that applies elsewhere.
The surface narrative holds a verdict and a feeling. The fuller review holds far more: the decisions behind each failure, the alternatives, the point of no return, the first warning, the corrected prediction and a pattern that may apply elsewhere, and each of those can inform a later decision. That is why years of experience can be a noisy hiring signal: ten years of recording outcomes may supply less usable information than six months of carefully examining them.
The Extraction Stack
The methods address different omissions in an initial account. A written record makes comparison possible; a prediction gives that comparison a fixed starting point; a question directs attention to information that might otherwise never enter the record. Will's model treats their combined effect as compounding.
1. Signal Amplification: Journaling
A vague feeling is difficult to examine because it changes while you think about it. Writing gives the feeling a stable description that can be compared with another day. Articulating “I feel stuck” for five minutes appears to force questions about what is stuck, why it is stuck, and what getting unstuck would involve.
In the example, ten minutes of journaling turns “I feel unmotivated today” into a more specific account. Starting work is taking a great deal of effort, the morning has no bridge into work, and the current state is being compared with yesterday's peak productivity. The missing launch ritual becomes an intervention the person can make, whereas “low motivation” alone does not explain what to change.
Will's Day 12 work-reactivation entry preserves both the observation and the proposed test:
"Activation cost for work still ~5 units. Mechanism: no launch ritual installed yet. Missing bridge between morning routine and work state. Prediction: installing 5-min review-of-yesterday's-progress as bridge will drop cost to ~2 units by day 15. Test starting tomorrow."
The record contains a causal explanation and an emotional description rather than only “work felt hard.” The journal also retains information across days. Working memory holds about 7 items, while a month contains hundreds of relevant observations. Externalizing them allows comparisons that introspection alone cannot hold in view. Will values journaling for making implicit information explicit and enabling those comparisons.
2. Question-as-Query Engineering
A question affects what receives attention during an experience. Entering a meeting with “What did I predict vs. what happened?” gives the person a comparison to make as events unfold. Without that question, the meeting may end with “that went okay” and no record of a mistaken expectation.
The question determines which dimension is examined:
- “What is the mechanism?” directs attention to causal structure.
- “What would have to be true for X?” examines counterfactuals.
- “What class of problem is this?” searches for a pattern category.
- “Where else have I seen this?” searches for a transfer to another situation.
- “What would I predict here, and what actually happens?” exposes prediction errors.
Loading a question takes about 30 seconds before the situation begins. The pattern-matching system then searches for the relevant information during the experience, rather than relying entirely on a later review.
3. Prediction Pre-registration
Memory can revise an expectation after the outcome arrives. “I knew that would happen” feels true even when the earlier prediction was different. A prediction written beforehand remains available for comparison and prevents most of that hindsight editing.
For example, the prediction might be that the 30x30 gym pattern will lower activation cost from high to almost nothing by Day 30. On Day 30 it is almost nothing, as predicted. The recorded prediction lets the person confirm the model and carry greater confidence into another domain.
Without the earlier record, “I figured it would get easier” can replace an original belief that it would never get easier. That removes the surprise and the model update. Tracking provides a record that the brain's narrative cannot edit; pre-registration gives the later numbers an expectation to test. Will rates this the most valuable of the seven methods, for the information it gives about prediction error and model validity.
4. Contrastive Pairing
A journal permits comparison between similar situations in which one condition differs. The useful questions are what was present in successes but absent in failures, and what was present in failures but absent in successes.
The gym comparison holds schedule, gym and exercises roughly constant. Without Julius as a forcing function, the gym happens on a few days out of 30. With Julius, it happens on nearly all of them. The comparison attributes the difference to his accountability, identifying a likely causal variable and the alternative outcome without it.
Without the comparison, the explanation can collapse into “I wanted it more this time.” That gives another person nothing specific to reproduce. Comparing the entries identifies the condition to test in another routine.
5. Mental Model as Bootstrap Simulator
Experience also supplies models that can make predictions about situations not yet encountered. A successful gym routine suggests that consistent daily execution reduces activation cost over about 30 days. Applying the model to meditation produces a prediction: the cost of starting to meditate should fall the same way, from high to almost nothing by Day 30.
A 30-day meditation experiment can then measure the actual trajectory. Success broadens the model's applicable domain. Failure raises a different question about which condition prevented the transfer. The simulation is followed by another real sample, and its accuracy determines the next model update.
This use of mental models extracts a transferable pattern from one experience and generates a test in another. It extends learning beyond the original sample without treating the simulated result as an observed result.
6. Resolution Matching
“My month was productive” averages away most of the information needed for an intervention. A note that anxiety rose slightly at 3:47pm can have the opposite problem: variation at that scale overwhelms the pattern. “Deep work happened on 2 days in Week 1 and on 4 days in Week 2, after installing a morning ritual” preserves a change at a useful timescale.
When everything looks random, averaging may reveal a pattern. When everything looks like the same category, additional detail may separate different causes. If neither view suggests an intervention, the resolution is still wrong for the decision.
The useful resolution has a high signal-to-noise ratio. Daily habits call for daily tracking, weekly patterns for weekly reviews, and quarterly strategy for quarterly assessments. Matching the timescale makes temporal changes and probability distributions easier to see.
7. Causal vs. Correlational Extraction
“I exercise and feel energized” records two things occurring together. An explanation of what generates the energy identifies an intervention. A causal entry would trace the chain: exercise gets the blood moving, the body shifts into a different state, and that shift is felt as energy. Adding the timing condition makes the claim more specific, for example that morning exercise brings energy in the afternoon while evening exercise disrupts sleep.
The causal account explains both the process and the conditions under which it acts. A correlation alone does not say which variable would change the outcome. Cybernetic control depends on that distinction because a variable that merely accompanies an outcome does not provide causal control over it.
Causal extraction is the step from co-occurrence to mechanisms that support intervention.
How the Methods Compound
Each method adds something different to the record:
| Extraction Method | What it adds to the record |
|---|---|
| Baseline (surface narrative) | The outcome and how it felt |
| + Journaling | A stable description that can be compared across days |
| + Pre-loaded questions | Attention directed while the experience is happening |
| + Prediction pre-registration | A fixed expectation to set the outcome against |
| + Contrastive pairing | The condition that differed between a success and a failure |
| + Mental model simulation | A prediction to test in a domain not yet tried |
| + Resolution matching | A timescale at which the pattern is visible |
| + Causal extraction | An account of what to change |
Not every method applies to every experience. The intended principle is that the methods compound; even half the stack is expected to provide far more information than default processing.
Fast Experience vs. Slow Experience
Fast Experience (Micro-loops)
Daily habit tracking supplies 365 samples a year. Per-repetition video review, test-driven development with minutes between iterations, and daily weight measurements also provide frequent feedback. Many samples cross the noise floor sooner, reduce variance and increase statistical power. Short feedback delay allows a model to update quickly.
These loops test a narrow range of conditions. They can miss changes at a larger timescale, and recording or reviewing each sample imposes an overhead that limits how many samples are practical.
Slow Experience (Macro-loops)
Career changes may happen only 3–5 times in a lifetime. Major relationship transitions, business pivots separated by years, and changes of life phase provide similarly infrequent feedback. A five-year cycle supplies 0.2 samples per year.
These experiences test large interventions that a daily experiment cannot reproduce. They also reveal long-term dynamics, and their stakes increase motivation and attention. However, N=3 career changes cannot provide much statistical confidence. Many conditions change during the delay, making it difficult to attribute an outcome to a particular decision.
The Synthesis: Nested Loops
A 30-day experiment can fit inside a five-year career arc. Tracking engagement daily in different domains supplies frequent observations relevant to career fit before a whole career outcome is available. The small experiments inform the larger decision without waiting for a lifetime of career changes.
In the comparison, a person running 20 short experiments in a year extracts more career-relevant information than someone who waits ten years for one career outcome. The fast and slow loops serve different functions: the shorter ones provide enough samples to detect patterns, and the longer one tests the consequential decision those patterns inform.
Compressing Years
Compare one person who spends ten years recording outcomes and feelings with another who spends one year journaling, loading questions, writing predictions and comparing entries. The second can come away with more information in one-tenth the time. More generally, two years of deliberate extraction can outperform ten years of passive accumulation because elapsed time does not measure what was learned.
Learning depends on the frequency and delay of feedback, the information extracted from each cycle, and the quality of the sample. A repetitive experience and a high-information experience need not teach equally much.
Each of the three can be changed: more feedback cycles per unit time, more information extracted per sample, and experiences chosen for the information they provide.
Common Extraction Failures
Review has diminishing returns. Spending two hours extracting lessons from a ten-minute experience can consume the time available for the next useful attempt; the stopping point is where another pass supplies little additional insight.
Journaling about the gym also cannot replace attending it. The review exists to inform action. Tracking the anxiety at 3:47pm while ignoring a weekly change in deep work similarly spends effort at an unhelpful resolution. Identifying a pattern without designing an intervention leaves the information unused.
Building Your Extraction Practice
Will's progression adds a method after the preceding one becomes automatic:
| Period | Practice |
|---|---|
| Weeks 1–2 | Ten minutes of unstructured journaling daily establishes externalization. |
| Weeks 3–4 | One question before a meeting or experience, beginning with “What is the mechanism here?”, directs attention during it. |
| Weeks 5–6 | Numerical predictions written before experiments can be compared with actual outcomes and their differences recorded. |
| Weeks 7–8 | Weekly reviews compare successes with failures; monthly reviews compare months. |
The remaining methods can be incorporated into those reviews. An existing model supplies a prediction before entering a new domain. Tracking detail can be adjusted to the decision's timescale. An observed correlation raises a question about the mechanism producing it.
A record of whether journaling happened is less informative than a record of what it revealed. “What do I know now that I didn't before?” identifies the change after an experience, and “What patterns emerged this week?” connects experiences across time.
Related Concepts
- Journaling makes implicit information stable enough to inspect.
- Tracking records distributions at a useful resolution.
- Question theory explains how a question directs attention.
- Skill acquisition examines learning from feedback and transfer.
- Information theory supplies the signal, noise and uncertainty distinctions.
- Predictive coding develops the role of prediction errors in learning.
- Cybernetics connects feedback timing to controllable variables.
- Optimal foraging theory examines exploration and exploitation when selecting experiences.
- Causality programming traces the mechanisms that generate outcomes.
- Modeling concerns the models used to generate further predictions.
- The 30x30 pattern supplies the month-long experiment used in several examples.
- Working memory explains why comparisons need an external record.
- Signal boosting examines how repeated samples cross detection thresholds.